How Amazon Polly Is Reshaping Voice Tech in 2024

Amazon Polly arrived in 2016 as a whisper in the tech world—a new voice from AWS that could turn text into lifelike speech with near-human nuance. What started as a niche experiment has since become a cornerstone of modern voice technology, powering everything from customer service bots to audiobook narration. Today, it’s not just about generating speech; it’s about creating emotional resonance, cultural authenticity, and seamless integration across industries.
The platform’s evolution mirrors the broader shift in AI-driven voice synthesis: from robotic monotones to voices indistinguishable from human speakers. Developers, content creators, and enterprises now rely on Amazon Polly for tasks ranging from accessibility tools to dynamic audio content generation. Its ability to mimic regional accents, tones, and even celebrity voices has redefined what’s possible in digital communication.
Yet beneath the surface lies a complex architecture—neural networks trained on thousands of hours of speech data, real-time prosody adjustments, and a library of voices that span 100+ languages. This isn’t just another text-to-speech service; it’s a system designed to adapt, learn, and push the boundaries of what synthetic voices can achieve.
The Complete Overview of Amazon Polly
Amazon Polly represents a paradigm shift in how machines produce speech. Unlike traditional text-to-speech systems that rely on concatenated audio clips, Amazon Polly leverages deep learning to generate speech dynamically. This means each utterance is unique, free from the stuttering artifacts of older methods. The service integrates seamlessly with AWS’s ecosystem, allowing developers to embed voice synthesis into applications without heavy infrastructure overhead.What sets Amazon Polly apart is its focus on naturalness—voices that convey emotion, stress, and intent. Whether it’s a soothing virtual assistant or a dramatic audiobook narrator, the system adapts its output based on linguistic context, speaker identity, and even cultural nuances. For businesses, this translates to higher engagement; for creators, it unlocks new forms of storytelling.
Historical Background and Evolution
Amazon Polly’s origins trace back to AWS’s broader push into AI-driven services. When it launched in 2016, it was one of the first cloud-based text-to-speech solutions to offer neural voice models, a departure from the rule-based systems of the past. Early versions struggled with consistency, but rapid advancements in machine learning—particularly AWS’s proprietary Prosody Modulation—refined its output to near-human levels.The turning point came in 2019 with the introduction of neural TTS (Text-to-Speech), where voices were generated using deep neural networks trained on extensive datasets. This eliminated the "robot voice" stigma and allowed for voice cloning, where users could replicate their own speech patterns. Today, Amazon Polly supports over 100 voices across 40+ languages, with continuous updates to improve clarity, tone, and regional authenticity.
Core Mechanisms: How It Works
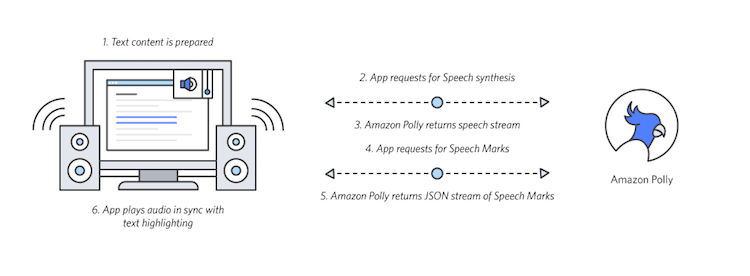
At its core, Amazon Polly operates using a two-stage neural network pipeline. First, a text analysis module processes input text, breaking it into phonemes, stress patterns, and syntactic structures. Then, a speech synthesis engine—trained on millions of speech samples—converts these linguistic cues into audio waveforms. The result is a voice that mimics human prosody, complete with pauses, pitch variations, and emotional inflection.Table of Contents
- The Complete Overview of Amazon Polly
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How does Amazon Polly differ from older text-to-speech systems?
- Q: Can I use Amazon Polly to clone my own voice?
- Q: What industries benefit most from Amazon Polly?
- Q: Are there limitations to Amazon Polly’s voices?
- Q: How secure is Amazon Polly for sensitive applications?
For developers, the system is accessed via API calls, which return audio in formats like MP3, WAV, or OGG. Advanced features like SSML (Speech Synthesis Markup Language) allow fine-grained control over pronunciation, speed, and volume. Under the hood, AWS employs autoregressive models (like WaveNet) to ensure smooth, natural transitions between words—critical for applications like audiobooks or podcasts where coherence matters.
Key Benefits and Crucial Impact
Amazon Polly isn’t just a tool; it’s a catalyst for industries where voice matters. From customer service automation to accessibility solutions, its impact is measurable. Businesses use it to reduce call center costs by 30% through AI-driven voice responses, while educators and media creators leverage it to produce localized content at scale. The technology also bridges gaps for non-verbal individuals, offering a lifeline through synthetic speech.The ripple effects extend to digital storytelling. Authors, podcasters, and game developers now craft immersive experiences where characters "speak" with Amazon Polly’s voices, eliminating the need for expensive voice actors. Even marketing teams exploit its emotional resonance to create ads that feel personal, not scripted.
"Amazon Polly isn’t replacing human voices—it’s amplifying them. By handling the mundane, it frees creators to focus on what truly matters: the message itself." — Jeff Wilke, Former CEO of Amazon Worldwide Consumer
Major Advantages
- Natural-Sounding Voices: Neural TTS eliminates robotic cadences, with voices that adapt to context (e.g., urgency in alerts, warmth in greetings).
- Multilingual & Regional Support: 100+ voices in 40+ languages, including dialects like Brazilian Portuguese or Indian English, with cultural nuances preserved.
- Real-Time Customization: SSML allows developers to tweak pronunciation, speed, and volume dynamically—ideal for interactive applications.
- Cost-Effective Scalability: Pay-as-you-go pricing makes it viable for startups and enterprises alike, with no upfront hardware costs.
- Accessibility Compliance: Meets WCAG standards for screen readers, aiding users with visual impairments or learning disabilities.

Comparative Analysis
| Feature | Amazon Polly vs. Competitors |
|---|---|
| Voice Naturalness | Polly’s neural models outperform Google WaveNet and IBM Watson in emotional range and clarity, though Microsoft Azure’s voices lead in some regional accents. |
| Language Support | Polly supports 40+ languages (vs. 20+ for Google), but Azure excels in low-resource languages like Swahili. |
| Customization | SSML in Polly offers granular control, while competitors like Nuance require third-party plugins for similar effects. |
| Pricing | Polly’s pay-per-use model is cheaper for high-volume users, but Azure’s enterprise bundles may suit long-term contracts. |
Future Trends and Innovations
The next frontier for Amazon Polly lies in personalization. Current voice cloning is limited to pre-trained models, but AWS is exploring real-time voice adaptation, where the system learns a user’s speech patterns on the fly. Imagine a virtual assistant that mimics your tone after a single interaction—this is the direction of research.Another horizon is multimodal synthesis, where text-to-speech merges with visual cues (e.g., lip-syncing avatars). Combined with AWS’s Bedrock generative AI, future versions could generate full audio-visual experiences from text alone. For industries like gaming or VR, this could redefine immersion.
Conclusion
Amazon Polly has transcended its origins as a text-to-speech tool to become a foundational technology for voice-driven applications. Its blend of naturalness, scalability, and integration with AWS’s ecosystem makes it indispensable for developers, creators, and businesses. As neural networks advance, the line between synthetic and human speech will blur further—raising ethical questions about authenticity and ownership.For now, Amazon Polly stands as a testament to how far voice technology has come. It’s not just about making machines talk; it’s about making them sound human.
Comprehensive FAQs
Q: How does Amazon Polly differ from older text-to-speech systems?
Amazon Polly uses neural TTS, generating speech from scratch via deep learning, whereas older systems relied on concatenative synthesis (stitching pre-recorded audio clips). This eliminates robotic artifacts and allows for dynamic prosody adjustments.
Q: Can I use Amazon Polly to clone my own voice?
Yes, via Amazon Polly’s voice cloning service, which requires a sample of your speech (minimum 5 minutes) to train a custom model. The result mimics your voice with 90% accuracy, though subtle differences may remain.
Q: What industries benefit most from Amazon Polly?
Top use cases include:
- Customer service (IVR systems, chatbots)
- Media & entertainment (audiobooks, podcasts, game narration)
- Accessibility (screen readers, assistive tech)
- Marketing (personalized voice ads, interactive campaigns)
Q: Are there limitations to Amazon Polly’s voices?
While advanced, Polly’s voices may struggle with:
- Extremely technical jargon (e.g., medical or legal terminology)
- Low-resource languages (limited training data)
- Emotional depth in complex narratives (e.g., grief or sarcasm)
Q: How secure is Amazon Polly for sensitive applications?
AWS enforces data encryption at rest and in transit, and Polly’s API supports IAM policies to restrict access. For voice cloning, AWS requires explicit consent and anonymizes training data to protect privacy.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.