Data Mining What Is Data Mining: The Hidden Logic Behind Smart Decisions

Every time you receive a personalized ad, a bank predicts your spending, or a healthcare system flags potential risks, an invisible force is at work—data mining what is data mining in its purest form. This isn’t just about collecting numbers; it’s about uncovering patterns hidden in vast datasets, turning raw information into actionable intelligence. The process has quietly revolutionized industries from finance to healthcare, yet most people remain unaware of its mechanics or implications.
At its core, data mining what is data mining refers to the systematic exploration of large datasets to identify correlations, market trends, or anomalies that would otherwise go unnoticed. Unlike traditional reporting, which answers predefined questions, data mining asks: What don’t we know yet? It’s the difference between reading a weather forecast and predicting a storm before it forms. The stakes are high—companies that master this technique gain competitive edges, while those that ignore it risk falling behind in an era where data is the new oil.
The irony? While data mining what is data mining powers innovations like fraud detection and drug discovery, its ethical gray areas—privacy concerns, bias in algorithms, and misuse of personal data—spark fierce debates. The technology itself is neutral; its impact depends on how it’s wielded. Understanding its workings isn’t just for data scientists—it’s essential for anyone navigating a world where decisions are increasingly driven by unseen algorithms.
The Complete Overview of Data Mining What Is Data Mining
Data mining what is data mining is a multidisciplinary field that blends statistics, machine learning, and database systems to extract meaningful insights from complex datasets. Unlike simple data queries, which retrieve pre-specified information, data mining employs automated techniques to discover patterns, classify information, and predict future trends. Think of it as a digital archaeologist sifting through mountains of data to uncover buried truths—whether it’s customer behavior, operational inefficiencies, or emerging market opportunities.
The term itself emerged in the late 1980s and early 1990s as businesses grappled with the explosion of digital data. What started as a niche academic pursuit—rooted in database theory and artificial intelligence—quickly became a cornerstone of corporate strategy. Today, data mining what is data mining underpins everything from recommendation engines (like Netflix’s suggestions) to high-frequency trading in financial markets. Its evolution mirrors the digital age: from batch processing in the 1990s to real-time analytics powered by cloud computing and AI.
Historical Background and Evolution
The origins of data mining what is data mining trace back to the 1960s with the rise of statistical learning and pattern recognition. Pioneers like IBM researcher John R. Velleman laid early groundwork, but the field gained momentum in the 1980s with the advent of relational databases and tools like Association Rule Mining. The term "data mining" was popularized in a 1995 paper by Gregory Piatetsky-Shapiro, though the concept predates it by decades—even ancient civilizations used rudimentary forms of data analysis to track trade routes or agricultural yields.
Table of Contents
- The Complete Overview of Data Mining What Is Data Mining
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Is data mining legal, and what are the ethical concerns?
- Q: How does data mining differ from machine learning?
- Q: Can small businesses benefit from data mining?
- Q: What skills are needed to become a data miner?
- Q: What are the most common data mining techniques?
- Q: How secure is data mining against breaches?
By the 2000s, the internet boom and the proliferation of sensors, social media, and e-commerce created an unprecedented volume of data. This era saw the birth of data mining what is data mining as a distinct discipline, with frameworks like Apache Hadoop and tools such as SAS Enterprise Miner democratizing access. The 2010s brought another paradigm shift: the integration of machine learning and deep learning, enabling systems to not just analyze data but learn from it autonomously. Today, data mining what is data mining is indistinguishable from AI, with models like neural networks sifting through terabytes of unstructured data—from images to natural language—to uncover insights once deemed impossible.
Core Mechanisms: How It Works
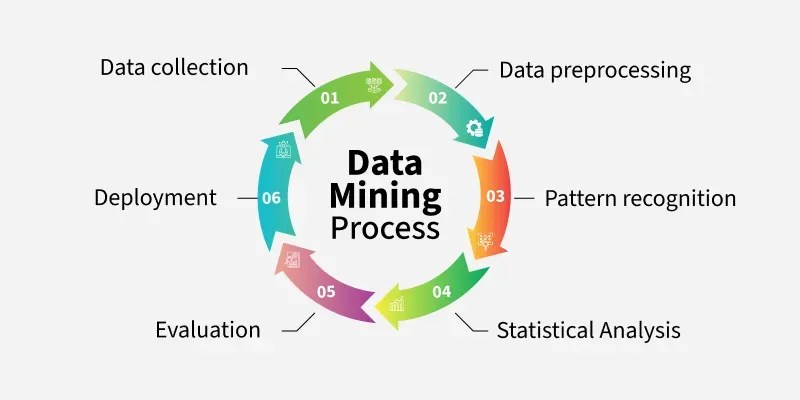
The process of data mining what is data mining begins with data collection, where raw inputs—structured (e.g., SQL databases) or unstructured (e.g., emails, videos)—are aggregated. The next phase, data preprocessing, cleans and transforms this data to remove noise, handle missing values, and normalize formats. For example, a retail dataset might combine transaction records, customer reviews, and social media mentions before analysis. This step is critical: garbage in, garbage out applies here with brutal precision.
Once preprocessed, the data enters the mining phase, where algorithms apply techniques like clustering (grouping similar data points), classification (categorizing records), or regression (predicting continuous outcomes). A classic example is market basket analysis, where retailers use association rules to determine which products customers buy together (e.g., diapers and beer). Advanced methods, such as deep learning for image recognition, now extend data mining what is data mining into domains like medical imaging or autonomous vehicles. The final output—whether a predictive model or a visualized trend—feeds back into decision-making, closing the loop between data and action.
Key Benefits and Crucial Impact
The value of data mining what is data mining lies in its ability to transform passive data into proactive strategies. For businesses, it’s the difference between reacting to market changes and anticipating them. In healthcare, it accelerates drug discovery by identifying molecular patterns in genomic data. Even governments leverage it to optimize public services, from traffic management to disease outbreak prediction. The impact isn’t just quantitative—it’s qualitative, reshaping industries by revealing hidden efficiencies, risks, and opportunities.
Yet the power of data mining what is data mining comes with responsibility. As data volumes grow, so do concerns about privacy, bias, and transparency. A poorly designed algorithm might reinforce discriminatory lending practices or misdiagnose diseases based on flawed training data. The challenge is balancing innovation with ethics—a tension that defines the future of the field.
"Data mining what is data mining isn’t about finding answers—it’s about asking the right questions in the first place."
— Rajeev Motwani, Stanford Professor and Data Mining Pioneer
Major Advantages
- Predictive Accuracy: Models trained on historical data (e.g., credit scoring) achieve precision rates exceeding 90% in some applications, reducing guesswork in high-stakes decisions.
- Cost Reduction: Identifying inefficiencies—such as supply chain bottlenecks or fraudulent transactions—saves companies millions annually by automating detection and optimization.
- Personalization: From Netflix’s recommendations to Spotify’s playlists, data mining what is data mining tailors experiences to individual preferences, increasing engagement and loyalty.
- Competitive Edge: Early adopters of data-driven strategies (e.g., Amazon’s demand forecasting) outperform competitors by anticipating market shifts before they occur.
- Scalability: Cloud-based tools like Google BigQuery or Snowflake enable organizations to process petabytes of data in minutes, making advanced analytics accessible to enterprises of all sizes.
Comparative Analysis
| Aspect | Data Mining | Traditional BI |
|---|---|---|
| Primary Goal | Discover unknown patterns/insights | Answer predefined questions |
| Data Type | Structured/unstructured (text, images, etc.) | Mostly structured (reports, dashboards) |
| Tools Used | Python (scikit-learn), R, Apache Spark | Tableau, Power BI, SQL queries |
| Output Example | Customer churn prediction model | Monthly sales performance report |
Future Trends and Innovations
The next frontier of data mining what is data mining lies in its fusion with emerging technologies. Quantum computing promises to accelerate complex calculations, enabling real-time analysis of datasets previously deemed impossible to process. Meanwhile, explainable AI (XAI) is addressing the "black box" problem, ensuring models remain transparent and auditable—a necessity for industries like healthcare and finance. Another trend is the rise of automated machine learning (AutoML), which lowers the barrier for non-experts to build sophisticated models without deep coding knowledge.
Ethically, the focus is shifting toward responsible data mining, with regulations like the EU’s GDPR and frameworks like AI ethics guidelines pushing for fairness, accountability, and privacy by design. As data grows more interconnected—through IoT devices, social networks, and digital twins—the line between data mining what is data mining and cybersecurity will blur further. The future won’t just be about extracting insights; it’ll be about securing, interpreting, and acting on them in an increasingly complex digital ecosystem.

Conclusion
Data mining what is data mining is more than a technical process—it’s a cultural shift in how we perceive and use information. From its humble beginnings in academic research to its current role as the backbone of global industries, its trajectory reflects humanity’s relentless pursuit of knowledge. The key to harnessing its potential lies in balancing innovation with integrity: using data to solve problems, not just profit from them.
As we stand on the brink of a data-driven future, the question isn’t whether to adopt data mining what is data mining, but how to do so responsibly. The tools are here; the challenge is ensuring they serve humanity’s highest goals—whether in curing diseases, combating climate change, or simply making smarter decisions. The data is waiting. The choice is ours.
Comprehensive FAQs
Q: Is data mining legal, and what are the ethical concerns?
A: Legality depends on jurisdiction and consent. In the EU, GDPR strictly regulates data collection and usage, requiring explicit user consent. Ethical concerns include privacy violations (e.g., Cambridge Analytica), algorithm bias (e.g., racial disparities in loan approvals), and misinformation (e.g., deepfake-generated data). Best practices involve anonymization, transparency, and adherence to frameworks like the Fair Information Practice Principles (FIPPs).
Q: How does data mining differ from machine learning?
A: While data mining what is data mining focuses on extracting patterns from data, machine learning (ML) is a subset that enables systems to learn and improve from experience. Data mining often uses ML algorithms (e.g., decision trees), but ML can operate without explicit mining—such as in reinforcement learning. Think of data mining as the "hunting" phase and ML as the "training" phase.
Q: Can small businesses benefit from data mining?
A: Absolutely. Tools like Google Analytics, HubSpot, or open-source platforms (KNIME, Orange) allow small businesses to analyze customer data, optimize marketing, and predict trends without large budgets. The key is starting small—e.g., using association rule mining to identify best-selling product bundles—before scaling up.
Q: What skills are needed to become a data miner?
A: Core skills include:
- Programming: Python (Pandas, NumPy), R, or SQL
- Statistics/Math: Probability, linear algebra, and hypothesis testing
- Domain Knowledge: Understanding the industry (e.g., healthcare, finance) to ask relevant questions
- Data Visualization: Tools like Tableau or Matplotlib to communicate insights
- Ethical Awareness: Knowledge of bias mitigation and privacy laws
Q: What are the most common data mining techniques?
A: The five primary techniques are:
- Classification: Categorizing data (e.g., spam detection)
- Clustering: Grouping similar records (e.g., customer segmentation)
- Regression: Predicting continuous values (e.g., house prices)
- Association Rule Learning: Finding relationships (e.g., "Customers who buy X also buy Y")
- Anomaly Detection: Identifying outliers (e.g., fraudulent transactions)
Q: How secure is data mining against breaches?
A: Security risks stem from data leakage (exposing sensitive info during preprocessing) or model poisoning (malicious input corrupting training data). Mitigation strategies include:
- Encryption (e.g., homomorphic encryption for secure computations)
- Access controls (role-based permissions)
- Differential privacy (adding noise to datasets to prevent re-identification)
- Regular audits using tools like Apache Griffin for anomaly detection
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.