How y as a function of x Shapes Reality—From Math to Life
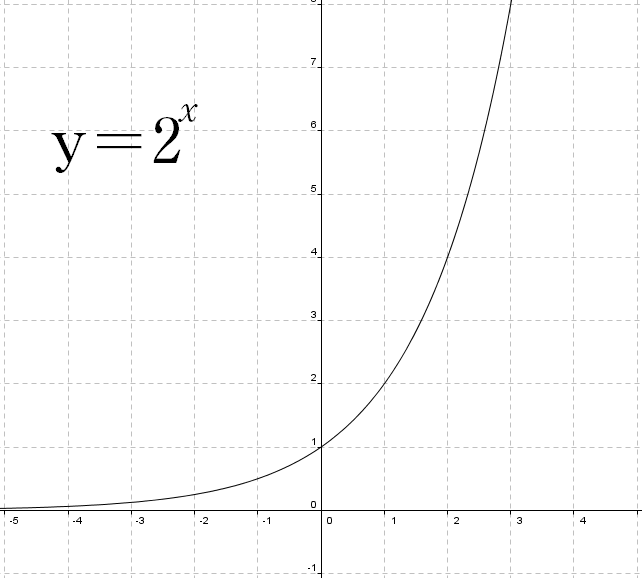
The equation y = f(x) is not merely a mathematical abstraction—it is the invisible architecture of causality itself. Whether you’re calculating the trajectory of a rocket, forecasting stock markets, or simply deciding how much coffee to brew before a meeting, you’re implicitly treating one variable as a consequence of another. The relationship between y and x is the language through which we model the world: a dependent variable shaped by an independent one, a response dictated by a stimulus, an outcome determined by its inputs.
Yet this deceptively simple notation carries centuries of intellectual weight. It bridges the gap between abstract theory and tangible outcomes, from Newton’s laws of motion to modern machine learning algorithms. The elegance lies in its universality—whether in the rise of GDP as a function of technological adoption or the stress levels of an employee as a function of workplace culture, the framework remains the same. The question is never whether y depends on x, but how—and what that reveals about the systems we inhabit.
The Complete Overview of "y as a Function of x"
At its core, y as a function of x is a statement of dependency—a way to express that one quantity’s value is entirely determined by another. This relationship can be linear, exponential, or chaotic, but the principle endures: x is the input, y the output, and the function f the rule governing their interaction. In mathematics, this is the bedrock of calculus, algebra, and statistical analysis; in practical terms, it’s the lens through which we interpret patterns, predict trends, and optimize systems.The power of this framework lies in its adaptability. It doesn’t just describe straight lines or parabolas—it models human behavior, ecological dynamics, and even the spread of information. A company’s profit margin as a function of marketing spend? A patient’s recovery rate as a function of treatment adherence? The same logic applies. By formalizing these relationships, we transform intuition into precision, turning vague correlations into actionable insights.
Historical Background and Evolution
The concept of functional relationships traces back to the 17th century, when mathematicians like René Descartes and Gottfried Leibniz sought to quantify change. Descartes’ La Géométrie (1637) introduced the Cartesian plane, where y became a visual representation of x’s influence—a breakthrough that democratized mathematical modeling. Meanwhile, Leibniz’s calculus formalized rates of change, allowing scientists to describe motion, growth, and decay with unprecedented accuracy.By the 19th century, the language of functions had permeated physics, economics, and engineering. Joseph Fourier’s heat equation demonstrated how temperature (y) varies with position and time (x), while Leonhard Euler’s work on differential equations laid the groundwork for modern dynamical systems. The 20th century expanded this further: Alan Turing’s computational models treated functions as algorithms, and John von Neumann’s game theory framed strategic outcomes as functions of player choices. Today, the framework underpins everything from climate modeling to social media recommendation engines.
Core Mechanisms: How It Works
The mechanics of y as a function of x hinge on three components: the independent variable (x), the dependent variable (y), and the function itself (f). The independent variable is the cause or input—time, effort, capital, or any measurable factor. The dependent variable is the effect or output, shaped entirely by x. The function f defines the transformation: it could be a simple linear rule (y = 2x), a complex polynomial, or even a stochastic process where y depends on x plus random noise.What makes this framework robust is its ability to handle nonlinearity. A stock price as a function of market sentiment might follow a logarithmic curve; a city’s crime rate as a function of police patrols could exhibit a threshold effect. The key is identifying the correct f—whether through regression analysis, differential equations, or machine learning—to capture the relationship’s true nature. Without this precision, predictions become guesswork; with it, they become science.
Key Benefits and Crucial Impact
The ubiquity of y as a function of x stems from its ability to distill complexity into actionable relationships. In business, it transforms vague strategies into quantifiable outcomes—whether optimizing supply chains or pricing models. In medicine, it deciphers how drug dosages (x) affect patient responses (y), reducing trial-and-error risks. Even in personal finance, understanding how savings (y) scale with income (x) and spending habits (z) is a function of disciplined data interpretation.Table of Contents
- The Complete Overview of "y as a Function of x"
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can y as a function of x handle randomness?
- Q: How do I determine the correct function f for my data?
- Q: What’s the difference between y as a function of x and x as a function of y ?
- Q: Can multiple x variables influence y ?
- Q: How does y as a function of x apply to non-quantitative fields like literature or psychology?
- Q: What are the ethical risks of assuming y is solely a function of x ?
This framework doesn’t just describe reality; it reshapes it. Policymakers use it to model the impact of taxes on GDP growth. Engineers rely on it to design bridges that withstand stress as a function of material properties. The ripple effects are profound: by formalizing cause and effect, we gain the power to intervene, optimize, and innovate.
"Mathematics is the art of giving the same name to different things." — Henri Poincaré
In the case of y as a function of x, that "same name" is dependency—a universal language for understanding how inputs generate outputs across disciplines.
Major Advantages
- Precision in Prediction: By defining y explicitly as a function of x, models reduce uncertainty. A retailer predicting sales (y) based on ad spend (x) can allocate budgets with statistical confidence.
- Causal Clarity: Correlation alone is ambiguous, but a well-specified function reveals causality. For example, if y (productivity) is a quadratic function of x (hours worked), managers can identify the optimal work duration before burnout sets in.
- Scalability: Functions are modular. A small business’s revenue model (y = f(x₁, x₂, ..., xₙ)) can scale to a multinational’s complex supply chain by adding more variables without losing structural integrity.
- Adaptability to Chaos: Even in nonlinear systems (e.g., weather patterns), functions help approximate behavior. Chaos theory itself studies how small changes in x can lead to wildly different y outcomes.
- Decision Optimization: Whether in logistics (y = delivery time as a function of route x) or healthcare (y = patient survival as a function of treatment x), functions provide the mathematical backbone for algorithms that minimize costs or maximize benefits.

Comparative Analysis
| Aspect | Linear Functions (y = mx + b) | Nonlinear Functions (y = f(x)) |
|---|---|---|
| Relationship Type | Constant rate of change (e.g., y increases by 2 for every 1 unit of x). | Variable rate (e.g., exponential growth, logarithmic decay). |
| Real-World Example | Simple interest calculations (y = principal + rate × time). | Population growth (y = P₀eᵗᵣ), where r* is the growth rate. |
| Modeling Complexity | Low; easy to solve analytically. | High; often requires numerical methods or simulations. |
| Limitations | Overestimates real-world scenarios where relationships aren’t uniform. | Requires more data and computational power to parameterize accurately. |
Future Trends and Innovations
The next frontier for y as a function of x lies in its intersection with artificial intelligence and big data. Machine learning models—particularly neural networks—automate the discovery of complex functions, where y depends on thousands of x variables (e.g., customer churn as a function of browsing history, location, and purchase patterns). These systems don’t just fit equations; they infer them from data, unlocking predictive power in domains once deemed too chaotic.Another horizon is dynamic functions—where f itself changes over time. In finance, a hedge fund’s strategy (f) might adapt to market volatility (x), making y (returns) a time-varying function. Similarly, in biology, gene expression (y) as a function of environmental stressors (x) can evolve, requiring adaptive modeling techniques. The future will see functions becoming more fluid, responsive, and integrated into real-time decision systems.

Conclusion
y as a function of x is more than a mathematical notation—it’s a philosophical toolkit for understanding how things influence each other. From the deterministic laws of physics to the probabilistic models of modern data science, the framework remains the same: identify the inputs, define the transformation, and predict the outputs. Its enduring relevance stems from its simplicity and its depth; it’s both a compass and a microscope, revealing patterns at every scale.As we move toward an era of hyper-connected systems, the ability to model y in terms of x—whether through classical equations or AI-driven approximations—will define the boundary between guesswork and insight. The challenge isn’t mastering the notation; it’s recognizing which variables to include, which to ignore, and how to wield the function to shape a better future.
Comprehensive FAQs
Q: Can y as a function of x handle randomness?
A: Yes, through stochastic functions. For example, y might equal f(x) + ε, where ε is a random error term. This is common in econometrics (e.g., stock returns as a function of market indices plus noise) or biology (growth rates with inherent variability).
Q: How do I determine the correct function f for my data?
A: Start with exploratory data analysis (EDA) to plot y vs. x and identify patterns (linear, polynomial, periodic). Use statistical tests (e.g., ANOVA) to compare models or employ machine learning algorithms like regression trees or neural networks for high-dimensional data. Domain knowledge is critical—e.g., a physicist might assume y follows a power law, while a marketer might test logarithmic decay.
Q: What’s the difference between y as a function of x and x as a function of y?
A: The distinction is causal directionality. y = f(x) implies x drives y (e.g., study time → exam scores), while x = g(y) reverses the relationship (e.g., exam scores → study time adjustments). In some cases, both may hold (e.g., supply and demand curves), but the function’s form often differs due to underlying mechanisms.
Q: Can multiple x variables influence y?
A: Absolutely. This is multivariate function notation: y = f(x₁, x₂, ..., xₙ). For example, house prices (y) might depend on square footage (x₁), location (x₂), and school quality (x₃). Techniques like multiple regression or partial least squares help isolate each x’s contribution.
Q: How does y as a function of x apply to non-quantitative fields like literature or psychology?
A: It’s used to model qualitative dependencies. In psychology, y (therapy success) might be a function of x (patient engagement + therapist empathy), even if measured on Likert scales. In literature, stylometry analyzes how word choice (y) varies with author (x) or genre. The key is operationalizing variables—turning abstract concepts into measurable inputs.
Q: What are the ethical risks of assuming y is solely a function of x?
A: Over-simplification can lead to reductionism. For example, treating crime rates (y) as a function of policing (x) ignores systemic factors like poverty or education. Ethical risks include:
- Ignoring confounding variables (e.g., assuming y depends only on x when z is the true driver).
- Justifying deterministic policies (e.g., "If x increases, y will always improve"), which may overlook randomness or feedback loops.
- Bias in data selection—if x and y are measured imperfectly, the function may reflect measurement error rather than true causality.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.