How to Split PDF Files: The Definitive Guide to Dividing Documents

PDFs dominate professional and personal workflows, yet their monolithic nature often clashes with practical needs. A single document may contain years of research, legal clauses spanning multiple sections, or a report too long for a single email attachment. The solution? Splitting PDFs—a precise, often underappreciated skill that transforms static files into flexible assets. Whether you’re a legal professional extracting case law, a researcher isolating key studies, or a business user segmenting client proposals, the ability to divide PDFs without losing formatting or metadata is indispensable.
The challenge lies in execution. Not all methods preserve hyperlinks, annotations, or embedded fonts. Some tools strip metadata, while others introduce unintended reflows. Worse, many users resort to manual cropping or printing—solutions that waste time and risk errors. The right approach depends on the document’s complexity, the desired output, and the tools at hand. This guide dissects the science behind PDF splitting, from historical roots to cutting-edge automation, ensuring you wield the technique with precision.
Consider the scenario: You’ve received a 300-page contract PDF, but only Pages 15–40 require review. Copying them manually risks misalignment; printing and rescanning degrades quality. A dedicated PDF splitter handles this in seconds, maintaining OCR layers, bookmarks, and even digital signatures. The difference between frustration and efficiency often hinges on knowing how to split—and why certain methods fail where others succeed.
The Complete Overview of Splitting PDF Files
At its core, splitting a PDF involves dissecting a single file into discrete segments while preserving structural integrity. The process leverages two primary mechanisms: page-based division and content-based extraction. Page-based splitting, the most common approach, separates documents by sequential pages, ideal for reports or manuals. Content-based splitting, however, uses metadata (e.g., bookmarks, headers) or text patterns to isolate chapters, tables, or even specific paragraphs—critical for legal or technical documents where context matters.
The tools and algorithms behind these methods have evolved from clunky command-line utilities to AI-driven workflows. Early solutions relied on brute-force page extraction, often corrupting embedded objects like forms or multimedia. Modern PDF splitting software employs lossless compression, intelligent page detection, and even machine learning to recognize logical breaks (e.g., chapter headings). The result? A process that balances speed with fidelity, catering to everything from batch processing to granular edits.
Historical Background and Evolution
The concept of PDF splitting emerged alongside the format itself, but practical tools lagged behind Adobe’s 1993 release. Initial attempts involved third-party scripts that parsed raw PDF data—a laborious task prone to errors. By the early 2000s, GUI-based utilities like PDF Split and Merge (PDFSAM) democratized the process, offering drag-and-drop interfaces. These tools, however, were limited to basic page ranges and lacked support for complex features like layered content.
Table of Contents
- The Complete Overview of Splitting PDF Files
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can I split a password-protected PDF?
- Q: Will splitting a PDF reduce its file size?
- Q: Are there free tools that preserve bookmarks and hyperlinks?
- Q: How do I split a PDF by odd/even pages?
- Q: Can I split a PDF and merge it back without data loss?
- Q: What’s the best way to split a scanned PDF?
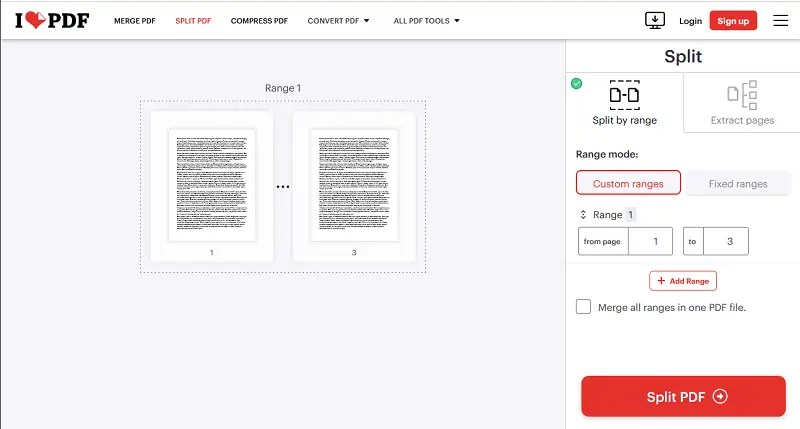
The turning point arrived with the rise of cloud-based solutions and APIs. Services like Smallpdf and iLovePDF introduced one-click PDF division via browser extensions, while enterprise platforms (e.g., Adobe Acrobat Pro) integrated splitting into broader document management suites. Today, the landscape includes open-source options (e.g., Ghostscript), proprietary tools (e.g., Nitro PDF), and even browser-native features (Chrome’s "Save as" with page ranges). The evolution reflects a shift from manual intervention to automated, scalable workflows—though legacy formats (e.g., scanned PDFs) still demand specialized handling.
Core Mechanisms: How It Works
Under the hood, splitting a PDF hinges on two layers: the file’s structural syntax and the tool’s parsing logic. PDFs are structured as a series of objects (text, images, vectors) referenced by a cross-reference table. When you split a document, the tool must reindex these objects, creating new cross-references for each segment. Failure here—often due to corrupted metadata—results in broken outputs. High-end PDF splitters use incremental updates to minimize reflow, ensuring fonts and graphics remain intact.
Content-aware splitting adds complexity. Tools like Adobe Acrobat analyze document properties (e.g., bookmark hierarchies) to infer logical divisions. For example, a research paper’s sections might be extracted based on heading styles rather than arbitrary page counts. This requires optical character recognition (OCR) for scanned files or semantic analysis for tagged PDFs. The trade-off? Precision comes at the cost of processing power, making batch operations slower. Understanding these mechanics explains why some methods excel with structured documents while others falter with unstructured data.
Key Benefits and Crucial Impact
The utility of PDF splitting extends beyond convenience—it’s a cornerstone of modern document workflows. Legal teams use it to isolate exhibits from briefs, while educators split textbooks into weekly modules. In archival contexts, splitting preserves original files while enabling selective sharing. The impact is measurable: reduced storage clutter, faster review cycles, and compliance with data-sharing regulations. Yet, the benefits are often overshadowed by misconceptions about complexity or quality loss.
Consider the case of a financial auditor reviewing a 500-page audit trail. Without PDF division, extracting relevant sections would take hours; with it, the task reduces to minutes. The same principle applies to e-discovery in litigation, where attorneys must cull thousands of pages without altering metadata. The right tool doesn’t just split—it preserves, a distinction that separates amateurs from professionals.
"Splitting a PDF isn’t just about dividing pages—it’s about maintaining the document’s DNA. A poorly executed split can turn a pristine legal contract into a jigsaw puzzle of misaligned clauses."
— Dr. Elena Vasquez, Document Forensics Specialist, Stanford University
Major Advantages
- Precision Control: Advanced PDF splitters allow granular divisions (e.g., "Extract all tables from Pages 10–50") using regex or metadata filters.
- Metadata Retention: Tools like PDFtk preserve author tags, creation dates, and custom properties, critical for auditing and version control.
- Batch Processing: Enterprise solutions handle hundreds of files simultaneously, ideal for publishing or data migration projects.
- Format Flexibility: Some splitters export to Word, Excel, or searchable PDFs, bridging legacy systems with modern workflows.
- Security Compliance: Redacted sections can be isolated and encrypted, aligning with GDPR or HIPAA requirements.
Comparative Analysis
| Tool/Method | Strengths & Weaknesses |
|---|---|
| Adobe Acrobat Pro | Pros: Preserves OCR, supports batch processing, integrates with cloud storage. Cons: Expensive; learning curve for advanced features. |
| Smallpdf (Web) | Pros: Free tier, one-click interface, no install. Cons: Limited to 2 files/hour; watermarks on free exports. |
| PDFtk (CLI) | Pros: Open-source, scriptable, preserves all metadata. Cons: Requires command-line expertise; no GUI. |
| Chrome’s "Save As" (Page Ranges) | Pros: Zero-cost, instant for simple splits. Cons: No metadata retention; breaks embedded forms. |
Future Trends and Innovations
The next frontier in PDF splitting lies in AI-driven automation. Current tools rely on static rules (e.g., "Split at every chapter heading"), but emerging systems use natural language processing to infer intent. For instance, a tool might recognize that "Section 3.2" in a patent document refers to a specific claim and extract it automatically—even if the heading style varies. Coupled with blockchain-based document hashing, this could enable tamper-proof splits for legal or medical records.
Hardware advancements will also play a role. Quantum computing may accelerate OCR for scanned PDFs, while edge computing could enable real-time splitting on mobile devices. For now, hybrid approaches—combining cloud processing with local encryption—offer the best balance of speed and security. The goal? A future where dividing PDFs is as seamless as copying a file, with zero trade-offs in quality or compliance.

Conclusion
The ability to split PDFs is no longer a niche skill but a fundamental competency in digital workflows. Whether you’re optimizing storage, streamlining reviews, or ensuring compliance, the right method transforms static documents into dynamic assets. The key is selecting tools that align with your document’s complexity and workflow demands—from Adobe’s enterprise-grade features to Smallpdf’s simplicity. As AI and automation reshape the landscape, the principles remain: precision, preservation, and purpose.
Start with a clear objective: Are you isolating a single page or restructuring an entire volume? Use the right tool for the job, and the result will be a split that’s as clean as the original. The tools are ready—now it’s your turn to wield them.
Comprehensive FAQs
Q: Can I split a password-protected PDF?
A: Yes, but only if you know the password. Tools like PDFtk or Adobe Acrobat require authentication to access the file’s contents. Scanned or encrypted PDFs may need additional OCR or decryption steps, which can degrade quality.
Q: Will splitting a PDF reduce its file size?
A: Not necessarily. While the number of files increases, each segment retains its original compression. However, if you re-save splits with optimized settings (e.g., lower resolution images), you may achieve savings—though this risks quality loss.
Q: Are there free tools that preserve bookmarks and hyperlinks?
A: Limited. Most free web-based PDF splitters (e.g., iLovePDF) strip interactive elements. For bookmark retention, use PDFtk with custom scripts or Adobe Acrobat’s "Export to PDF" feature, which honors document structure.
Q: How do I split a PDF by odd/even pages?
A: Advanced tools like PDFtk support this via command-line arguments (e.g., `pdfseparate -f 1 -t 2 input.pdf odd.pdf`). Adobe Acrobat’s "Print to PDF" dialog also allows page range selection with odd/even toggles.
Q: Can I split a PDF and merge it back without data loss?
A: Yes, but only if the splitting tool preserves metadata and object references. Adobe Acrobat’s "Combine Files into Single PDF" function works reliably for this, while free tools may introduce inconsistencies in page numbering or embedded fonts.
Q: What’s the best way to split a scanned PDF?
A: Use OCR-enabled tools like Adobe Scan or ABBYY FineReader before splitting. These convert text layers into editable formats, allowing precise extraction. Manual cropping in tools like GIMP is a fallback but lacks metadata support.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.