How Python's Null Values Reshape Data Handling and Debugging
Python’s treatment of python null values is a cornerstone of its flexibility, yet it remains one of the most misunderstood aspects for developers transitioning from statically typed languages. Unlike languages that enforce explicit null checks or throw exceptions at every `null` reference, Python embraces ambiguity—offering `None`, `NaN`, and empty containers as distinct representations of absence. This duality is both a strength and a pitfall: while it allows for expressive data modeling, it also introduces subtle bugs when developers conflate these concepts. The language’s design reflects a pragmatic approach, where the absence of data is treated not as an error but as a first-class citizen in logic flows.
The ambiguity extends beyond syntax. Consider a missing database record: should it be `None`, a `NaN` (Not a Number) in a pandas DataFrame, or an empty list? Python’s ecosystem—spanning libraries like NumPy, pandas, and SQLAlchemy—each define their own conventions, forcing developers to navigate a fragmented landscape. This inconsistency is not a flaw but a reflection of Python’s adaptability to diverse use cases, from scripting to large-scale data pipelines. Yet, the lack of a unified standard means that even experienced engineers often spend debugging time untangling why a `null` check fails when the value is technically `None` but treated as `NaN` in a downstream operation.
At its core, Python’s python null system is a study in trade-offs. The language prioritizes readability and dynamism over strict type safety, which explains why `None` is a singleton object rather than a type. This design choice simplifies memory management but requires developers to master context-specific behaviors—whether in conditional checks (`if x is None`), type annotations (`Optional[int]`), or library-specific null handling (e.g., SQLAlchemy’s `NULL` vs. `None`). The result is a toolkit powerful enough to handle everything from simple scripts to complex data science workflows, but only if developers understand the nuances of how absence is represented and processed.
The Complete Overview of Python Null Values
Python’s approach to python null values is defined by three primary constructs: `None`, `NaN` (from the `math` and `numpy` modules), and empty collections (lists, dictionaries, sets). While all represent "nothing," their behavior diverges sharply. `None` is a singleton object used to denote the absence of a value in a variable or return statement, whereas `NaN` (Not a Number) is a floating-point representation of undefined mathematical operations, commonly used in numerical computing. Empty collections, though visually similar to `None`, are distinct entities—an empty list `[]` is not the same as `None`, though both may evaluate to `False` in a boolean context. This distinction is critical: a function returning `[]` signals an empty result, while `None` implies the absence of any result at all.The complexity deepens when these constructs interact with Python’s type system. For instance, `None` can be annotated with `Optional[T]` to indicate a variable might be `None`, but this annotation is purely a hint—Python’s runtime ignores it. Meanwhile, `NaN` behaves unpredictably in comparisons: `NaN != NaN` evaluates to `True`, a quirk inherited from IEEE 754 floating-point standards. This inconsistency forces developers to adopt library-specific patterns, such as pandas’ `isna()` or `isnull()` methods, rather than relying on generic `is None` checks. The lack of a universal null-handling mechanism underscores Python’s philosophy: flexibility over rigidity, even at the cost of occasional ambiguity.
Historical Background and Evolution
The concept of python null values traces back to Python’s early days, when Guido van Rossum designed the language to avoid the pitfalls of C’s `NULL` pointer dereferencing. In Python 0.9.8 (1991), `None` was introduced as a single, immutable object representing the absence of a value, inspired by Lisp’s `nil`. This design choice was deliberate: unlike C’s `NULL`, which can lead to segmentation faults, Python’s `None` is a safe, explicit marker. The evolution continued with Python 2.0 (2000), which formalized `None` as a built-in constant, and later with Python 3.x, where type hints (`Optional[T]`) were added to clarify intent without enforcing runtime checks.The introduction of `NaN` in Python’s numerical ecosystem reflects a different lineage. Borrowed from the IEEE 754 standard for floating-point arithmetic, `NaN` was adopted by libraries like NumPy to handle undefined operations (e.g., `0.0 / 0.0`). This created a divergence: while `None` is a general-purpose null, `NaN` is domain-specific, tied to mathematical computations. The fragmentation became more pronounced with the rise of data science libraries, where pandas and Polars introduced their own null representations (e.g., `pd.NA` in pandas 1.0) to distinguish between missing data and undefined numerical values. This historical layering explains why Python’s python null landscape is a patchwork of conventions rather than a unified system.
Core Mechanisms: How It Works
Under the hood, Python’s python null values operate through distinct memory and comparison mechanisms. `None` is a singleton instance of the `NoneType` class, meaning all `None` references point to the same object in memory. This design optimizes memory usage but requires developers to use `is` or `is not` for identity checks rather than `==`, which would incorrectly evaluate to `True` for `None == None` (though this is functionally equivalent in practice). In contrast, `NaN` is a floating-point value (typically `0x7ff8000000000000` in IEEE 754 double-precision) with special comparison rules: `NaN` is not equal to itself, and operations involving `NaN` propagate the undefined state (e.g., `NaN + 5 = NaN`).Table of Contents
- The Complete Overview of Python Null Values
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How do I check if a variable is `None` in Python?
- Q: What’s the difference between `None` and `NaN` in Python?
- Q: Why does `NaN != NaN` evaluate to `True`?
- Q: How do I handle `None` values in a pandas DataFrame?
- Q: Can I use `None` as a default argument in a function?
- Q: What’s the best way to annotate optional null values in Python 3?
- Q: How do I convert between `None`, `NaN`, and empty collections?
- Q: Are there performance implications for using `None` vs. `NaN`?
Empty collections (`[]`, `{}`, `set()`) are distinct from `None` but share some behaviors. For example, an empty list evaluates to `False` in a boolean context, just like `None`. However, their memory representation is dynamic: `[]` is an instance of `list` with zero elements, not a singleton. This distinction becomes critical in operations like list concatenation (`[] + None` raises `TypeError`), where the absence of a value (`None`) cannot be merged with an empty sequence. Python’s handling of these cases reflects its emphasis on explicit over implicit behavior—developers must actively choose how to represent and process absence.
Key Benefits and Crucial Impact
The flexibility of Python’s python null system is its greatest asset, enabling developers to model real-world data where absence is meaningful. For example, a database query might return `None` for missing records, while a scientific computation could yield `NaN` for invalid measurements. This granularity allows Python to bridge gaps between scripting, data analysis, and systems programming without forcing artificial constraints. Libraries like pandas leverage this flexibility to create high-performance data structures where nulls are handled implicitly (e.g., `df.dropna()`), reducing boilerplate code for common operations.However, this flexibility comes with trade-offs. The lack of a unified null type means developers must constantly contextualize their checks. A `None` in a web API response might map to `NULL` in SQL, which could then be converted to `NaN` in a numerical pipeline—each step introducing potential for error. The ambiguity also complicates debugging: a silent failure in a `None`-aware function might go unnoticed until data downstream is corrupted. Despite these challenges, Python’s approach remains influential, shaping how modern languages like JavaScript (with `null`/`undefined`) and Rust (with `Option
"Python’s null values are a double-edged sword: they empower expressive code but demand discipline. The language trusts developers to use them correctly, which is why even seasoned engineers spend more time debugging null-related issues than they’d like to admit."
— Guido van Rossum (Python Creator)Major Advantages
Comparative Analysis
| Aspect | Python (None/NaN) | JavaScript (null/undefined) | Java (null) |
|---|---|---|---|
| Representation | `None` (singleton), `NaN` (floating-point) | `null` (object reference), `undefined` (uninitialized) | `null` (object reference), `NULL` (SQL-like) |
| Comparison Behavior | `None` uses `is`; `NaN != NaN` is `True` | `null == undefined` is `false`; loose equality (`==`) coerces | `null` comparisons are strict (`==` or `!=`) |
| Type System | Dynamic; `Optional[T]` is a hint | Dynamic; type hints (`| null`) are optional | Static; `NullPointerException` on dereference |
| Performance Impact | Lightweight (`None` is a singleton); `NaN` has IEEE 754 overhead | Minimal; `null`/`undefined` are reference types | High; `NullPointerException` is a runtime error |
Future Trends and Innovations
The future of python null handling is likely to focus on standardization and integration with modern tooling. Projects like PEP 701 (proposing a `Missing` type for optional values) aim to clarify distinctions between `None`, `NaN`, and missing data, reducing ambiguity in type annotations. Meanwhile, libraries are adopting more explicit null representations: for example, pandas’ `pd.NA` is designed to be distinct from `None` and `NaN`, paving the way for safer data operations. As Python’s type system evolves (e.g., with `typing.Optional` and `Union` types), we may see stricter null-handling patterns emerge, though the language’s core philosophy of flexibility will likely persist.Another trend is the integration of null handling with concurrency and async programming. As Python’s `asyncio` and `multiprocessing` modules mature, null values in distributed systems (e.g., `None` in shared memory) will require more robust synchronization mechanisms. Additionally, the rise of WebAssembly and Python’s growing role in embedded systems may introduce new null-handling paradigms, where memory constraints demand more efficient representations than `None` or `NaN`. Regardless of these shifts, Python’s python null system will continue to reflect its core strength: balancing expressiveness with the pragmatism needed for real-world applications.

Conclusion
Python’s treatment of python null values is a testament to its design philosophy: prioritize usability over orthodoxy. The language’s embrace of `None`, `NaN`, and empty collections as distinct yet related concepts allows developers to model absence in ways that static languages cannot. However, this flexibility demands vigilance—developers must understand the context in which null values appear, whether in a script, a data pipeline, or a numerical computation. The lack of a unified null type is often cited as a weakness, but it is also a feature, enabling Python to adapt to diverse domains without sacrificing performance or clarity.As Python evolves, the conversation around null handling will likely shift toward standardization and tooling support. Initiatives like PEP 701 and library-specific null types (e.g., `pd.NA`) suggest a move toward clearer distinctions, but the core challenge remains: how to maintain Python’s dynamic nature while reducing the cognitive load of null-related bugs. For now, developers must navigate this landscape with care, leveraging Python’s strengths while mitigating its ambiguities. The result is a tool that remains unparalleled in its ability to handle absence—whether as `None`, `NaN`, or something in between.
Comprehensive FAQs
Q: How do I check if a variable is `None` in Python?
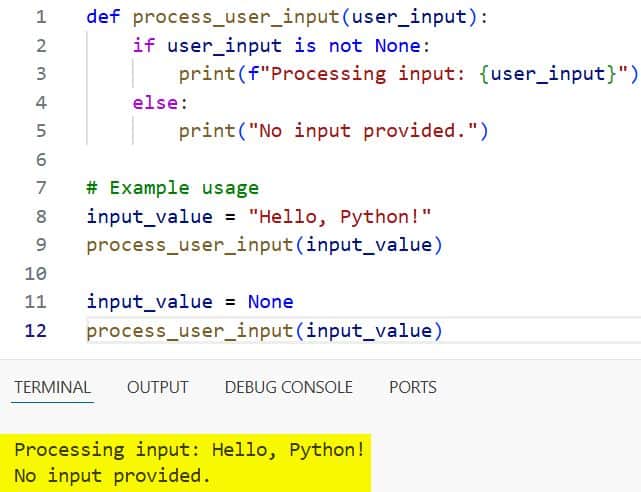
A: Use the `is` operator for identity checks: `if x is None`. Avoid `==` because `None == None` is technically `True`, but `is` is the idiomatic and safer choice. For example:
```python
if some_var is None:
print("Variable is explicitly null")
```
Q: What’s the difference between `None` and `NaN` in Python?
A: `None` is a singleton object representing the absence of a value, while `NaN` (Not a Number) is a floating-point value (from `math.nan` or `numpy.nan`) indicating undefined mathematical operations. Key differences:
- `None` can be compared with `is`; `NaN` cannot be compared to itself (`NaN == NaN` is `False`).
- `None` is used in general programming; `NaN` is domain-specific to numerical computations.
- `None` is a built-in constant; `NaN` requires importing from `math` or `numpy`.
Q: Why does `NaN != NaN` evaluate to `True`?
A: This behavior stems from the IEEE 754 floating-point standard, which defines `NaN` as a value that is not equal to any other value, including itself. Python adheres to this standard, so `NaN != NaN` is `True`. To check for `NaN`, use:
```python
import math
if math.isnan(x):
print("x is NaN")
```
Q: How do I handle `None` values in a pandas DataFrame?
A: Pandas provides dedicated methods for null handling:
- `df.isna()` or `df.isnull()`: Identify missing values (including `None`, `NaN`, and `pd.NA`).
- `df.dropna()`: Remove rows/columns with nulls.
- `df.fillna(value)`: Replace nulls with a specified value.
- `pd.NA`: A dedicated missing value type (introduced in pandas 1.0) that behaves differently from `None` and `NaN`.
```python
import pandas as pd
df = pd.DataFrame({"A": [1, None, 3]})
df_cleaned = df.dropna()
```
Q: Can I use `None` as a default argument in a function?
A: Yes, but be cautious. Default arguments are evaluated once at function definition time, so mutable defaults (like `None`) can lead to unexpected behavior if reassigned. For example:
```python
def func(x=None):
if x is None:
x = [] # Safe, as `None` is immutable
x.append(1)
return x
```
However, avoid:
```python
def bad_func(x=[]): # Dangerous: `x` retains state between calls
x.append(1)
return x
```
Q: What’s the best way to annotate optional null values in Python 3?
A: Use `typing.Optional[T]` or the union type `T | None` (Python 3.10+). For example:
```python
from typing import Optional
def process_data(data: Optional[list]) -> None:
if data is None:
raise ValueError("Data cannot be null")
```
Or in Python 3.10+:
```python
def process_data(data: list | None) -> None:
...
```
This clarifies intent without enforcing runtime checks (Python remains dynamically typed).
Q: How do I convert between `None`, `NaN`, and empty collections?
A: The conversions depend on context:
- `None` ↔ `NaN`: No direct conversion; treat them as distinct. Use `math.isnan()` to detect `NaN`.
- `None` ↔ empty collections: Explicit checks are needed. For example:
```python
if not some_list: # Checks for both `None` and empty list
pass
```
To distinguish:
```python
if some_list is None:
print("Explicitly null")
elif not some_list:
print("Empty list")
``` - SQL `NULL` ↔ Python `None`: Libraries like SQLAlchemy handle this automatically during ORM operations.
Q: Are there performance implications for using `None` vs. `NaN`?
A: Yes. `None` is a lightweight singleton with minimal overhead, while `NaN` involves floating-point operations and adheres to IEEE 754 rules, which can introduce slight performance costs in numerical computations. For example:
- Checking `x is None` is faster than `math.isnan(x)`.
- Operations on `NaN` (e.g., arithmetic) propagate the undefined state, which may slow down vectorized computations in NumPy.
- In data pipelines, `pd.NA` (pandas’ missing value type) is optimized for performance but requires explicit handling.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.