Mastering Python Set Operations: A Deep Dive into Different Methods for Data Handling

Python’s set data structure is a powerhouse for developers working with python set different methods data—offering unparalleled efficiency in handling uniqueness, membership checks, and mathematical operations. Unlike lists or dictionaries, sets inherently enforce uniqueness, making them ideal for deduplication, filtering, and set-theoretic computations. Whether you’re optimizing a database query, cleaning messy datasets, or implementing algorithmic logic, understanding how to manipulate sets with precision is non-negotiable.
The elegance of Python’s set operations lies in their simplicity and speed. A single method call can replace hours of manual iteration, reducing both code complexity and execution time. For instance, removing duplicates from a list of 10,000 entries takes milliseconds with `set()`, whereas a brute-force loop would introduce latency and readability issues. This efficiency isn’t just theoretical—it’s a cornerstone of scalable applications, from web scraping tools to machine learning pipelines.
Yet, beyond basic operations like union and intersection, Python’s set library hides advanced functionalities that most developers overlook. Methods like `symmetric_difference`, `update`, and `difference_update` unlock nuanced control over data relationships, enabling solutions tailored to specific problems. The key to leveraging these tools lies in recognizing when to use each method—and why.
The Complete Overview of Python Set Operations
Python’s set operations are built on mathematical set theory, providing a direct translation of concepts like subsets, supersets, and Cartesian products into code. At its core, a set is an unordered collection of unique, immutable elements, which makes it distinct from lists (ordered, mutable) or dictionaries (key-value pairs). The python set different methods data framework allows developers to perform operations such as merging, filtering, and comparing sets with minimal overhead, thanks to Python’s optimized C-based implementation.The power of sets becomes evident when dealing with large datasets. For example, identifying common elements between two datasets (intersection) or unique elements in either dataset (symmetric difference) can be achieved in constant time, O(n), where n is the size of the set. This efficiency is critical in domains like bioinformatics, where datasets often exceed millions of entries. Moreover, sets automatically handle hashability, ensuring that only immutable types (e.g., tuples, strings, numbers) can be stored, which prevents runtime errors from mutable objects like lists.
Historical Background and Evolution
The concept of sets traces back to Georg Cantor’s 19th-century work on infinite sets, but their computational implementation evolved with early programming languages. Python’s set operations were introduced in Python 2.3 (2003) as part of the built-in `set` and `frozenset` types, replacing the older `MutableSet` from the `sets` module. This shift marked a turning point, as it standardized set operations across the language and integrated them with built-in functions like `len()` and iteration protocols.Before Python’s native sets, developers relied on workarounds—such as converting lists to tuples and using dictionary keys—leading to verbose and error-prone code. The introduction of `set()` and methods like `add()`, `remove()`, and `pop()` democratized set operations, making them accessible to both beginners and experts. Over time, additional methods were added to address gaps, such as `symmetric_difference` (Python 2.6) and `update()` variants, which refined the toolkit for python set different methods data manipulation.
Core Mechanisms: How It Works
Under the hood, Python sets are implemented as hash tables, where each element’s hash value determines its storage location. This design ensures O(1) average-time complexity for membership tests (`x in s`) and O(n) for operations like union or intersection, where n is the size of the larger set. The immutability requirement for set elements stems from this hash-based storage: mutable objects (e.g., lists) cannot be hashed, as their memory address changes during modification.Table of Contents
- The Complete Overview of Python Set Operations
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: How do I remove duplicates from a list using sets?
- Q: What’s the difference between `remove()` and `discard()` in sets?
- Q: Can I use sets with mutable objects like lists or dictionaries?
- Q: How does `symmetric_difference` differ from `difference_update`?
- Q: Are there performance differences between `set1 | set2` and `set1.union(set2)`?
- Q: How can I check if two sets are disjoint (no common elements)?
- Q: What’s the fastest way to find common elements between two large sets?
- Q: Can I use sets to find the Cartesian product of two collections?
- Q: How do I convert a set to a frozenset?
- Q: What happens if I try to add a duplicate to a set?
- Q: Are there any memory trade-offs when using sets for deduplication?
When performing operations like `set1 | set2` (union), Python internally creates a new set by combining elements from both, automatically resolving duplicates. Similarly, `set1 & set2` (intersection) iterates through one set and checks for membership in the other. The `update()` method modifies the original set in-place, while `union()` returns a new set, reflecting Python’s philosophy of immutability by default. This distinction is crucial for memory management, especially in large-scale applications.
Key Benefits and Crucial Impact
The adoption of python set different methods data techniques has revolutionized how developers handle uniqueness and relationships in datasets. In data science, sets are used to preprocess raw data by eliminating duplicates, while in cybersecurity, they help detect anomalies by comparing known threat signatures against observed activity. The performance gains are equally significant: a set-based deduplication of 100,000 records can outpace a list-based approach by orders of magnitude.Beyond speed, sets simplify complex logic. For example, calculating the difference between two sets (`set1 - set2`) is equivalent to finding elements in `set1` not present in `set2`, a task that would require nested loops in other data structures. This clarity reduces debugging time and improves maintainability. As Python continues to dominate data-driven industries, mastery of set operations is no longer optional—it’s a competitive advantage.
"Sets are to data manipulation what Swiss Army knives are to survival tools—compact, versatile, and indispensable for tackling problems you didn’t even know you had."
— Guido van Rossum (Python Creator, in a 2018 interview on Python’s evolution)
Major Advantages
- Deduplication in Linear Time: Converting a list to a set (`set(list)`) removes duplicates instantly, whereas manual loops require O(n²) comparisons.
- Memory Efficiency: Sets store only unique elements, reducing memory usage for large datasets compared to lists or dictionaries.
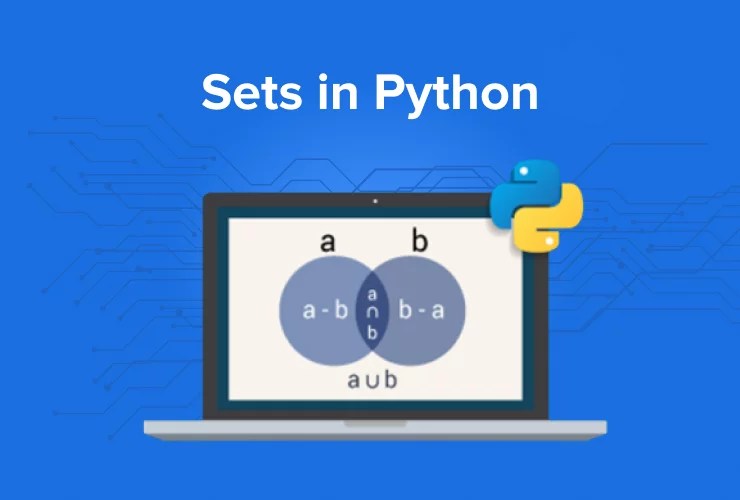
- Mathematical Precision: Operations like union (`|`), intersection (`&`), and difference (`-`) mirror set theory, ensuring logical accuracy in algorithms.
- Immutable Operations: Methods like `union()` return new sets, preserving the original data and enabling functional programming patterns.
- Integration with Built-ins: Sets work seamlessly with functions like `map()`, `filter()`, and comprehensions, expanding their utility beyond standalone operations.

Comparative Analysis
| Method | Use Case | Performance | Mutability ||--------------------------|-----------------------------------------------------------------------------|--------------------------|-----------------------|
| `add(element)` | Insert a single element into the set. | O(1) | Modifies the set |
| `update(iterable)` | Add multiple elements from an iterable (e.g., list, tuple). | O(n) | Modifies the set |
| `remove(element)` | Delete a specific element; raises `KeyError` if missing. | O(1) | Modifies the set |
| `discard(element)` | Delete an element if present (no error if missing). | O(1) | Modifies the set |
| `pop()` | Remove and return an arbitrary element (raises `KeyError` if empty). | O(1) | Modifies the set |
| `clear()` | Remove all elements from the set. | O(1) | Modifies the set |
| `union(set2)` | Return a new set with all elements from both sets. | O(n + m) | Immutable |
| `intersection(set2)` | Return a new set with common elements. | O(min(n, m)) | Immutable |
| `difference(set2)` | Return elements in the set but not in `set2`. | O(n) | Immutable |
| `symmetric_difference()` | Return elements in either set but not in both. | O(n + m) | Immutable |
Future Trends and Innovations
As Python evolves, so too will the capabilities of python set different methods data handling. One emerging trend is the integration of set operations with parallel processing frameworks like Dask or Ray, enabling distributed deduplication across clusters. Additionally, type hints for sets (e.g., `Set[int]`) are becoming standard, improving code clarity and IDE support.Another frontier is probabilistic sets, which use hashing techniques to approximate set operations with reduced memory usage—a boon for big data applications. Libraries like `pyhashing` already experiment with these ideas, suggesting that future Python versions may include built-in probabilistic set types. For now, developers can leverage existing methods creatively, such as combining sets with generators for lazy evaluation in memory-constrained environments.
Conclusion
Python’s set operations are a testament to the language’s design philosophy: simplicity paired with raw power. Whether you’re optimizing a script for a startup or analyzing terabytes of scientific data, the python set different methods data toolkit provides the precision and speed needed to solve problems efficiently. The historical progression from ad-hoc workarounds to built-in sets underscores their importance, while future innovations promise to extend their reach into uncharted territories.Mastery of these methods isn’t just about writing cleaner code—it’s about unlocking performance bottlenecks and solving problems that would otherwise stall development. As Python’s ecosystem grows, so will the creative applications of sets, from real-time analytics to distributed systems. The time to explore these tools is now.
Comprehensive FAQs
Q: How do I remove duplicates from a list using sets?
A: Convert the list to a set and back to a list: `list(set(original_list))`. This works because sets automatically discard duplicates. For preserving order (Python 3.7+), use `dict.fromkeys(original_list)`.
Q: What’s the difference between `remove()` and `discard()` in sets?
A: `remove(element)` raises a `KeyError` if the element isn’t found, while `discard(element)` silently ignores missing elements. Use `discard()` when you’re unsure if the element exists.
Q: Can I use sets with mutable objects like lists or dictionaries?
A: No. Sets require elements to be hashable and immutable. Mutable objects (e.g., lists, dicts) cannot be hashed, so they’ll raise a `TypeError`. Use tuples or frozensets instead.
Q: How does `symmetric_difference` differ from `difference_update`?
A: `symmetric_difference()` returns a new set with elements in either set but not both, while `difference_update()` modifies the original set in-place to remove elements found in another set. The former is immutable; the latter is not.
Q: Are there performance differences between `set1 | set2` and `set1.union(set2)`?
A: No. Both methods perform the same operation under the hood, returning a new set with all unique elements. The `|` operator is syntactic sugar for `union()`, so choose based on readability.
Q: How can I check if two sets are disjoint (no common elements)?
A: Use `set1.isdisjoint(set2)`. This method returns `True` if the sets have no intersection, which is equivalent to `len(set1 & set2) == 0` but more efficient.
Q: What’s the fastest way to find common elements between two large sets?
A: Use `set1 & set2` (intersection). This operation runs in O(min(len(set1), len(set2))) time, making it optimal for large datasets. For iterative updates, consider `set1.intersection_update(set2)` to modify `set1` in-place.
Q: Can I use sets to find the Cartesian product of two collections?
A: Not directly. Sets don’t support Cartesian products natively, but you can use `itertools.product()` for this purpose: `list(itertools.product(set1, set2))`. Sets are unordered, so the result won’t preserve order.
Q: How do I convert a set to a frozenset?
A: Use `frozenset(set_object)`. A `frozenset` is an immutable version of a set, meaning it can be used as a dictionary key or stored in another set. Unlike regular sets, `frozenset` objects cannot be modified after creation.
Q: What happens if I try to add a duplicate to a set?
A: Nothing. Sets automatically ignore duplicate values, so calling `set1.add(x)` where `x` already exists will have no effect. This behavior is guaranteed by Python’s set implementation.
Q: Are there any memory trade-offs when using sets for deduplication?
A: Yes. Converting a large list to a set requires O(n) memory to store the unique elements. For extremely large datasets (e.g., >100GB), consider streaming approaches or probabilistic data structures like Bloom filters to reduce memory usage.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.