How to Build Databases: The Definitive Guide to Create Table SQL

Database architecture begins with a single command: CREATE TABLE. This deceptively simple SQL instruction is the bedrock of every structured dataset, from enterprise ERP systems to personal project trackers. Without it, data would remain fragmented—scattered across files or unlinked records. The ability to define tables with precise column types, constraints, and relationships transforms raw information into a functional resource. Yet for many developers, the transition from theoretical knowledge to practical implementation stumbles at the syntax stage. Understanding how to properly structure a CREATE TABLE statement isn’t just about memorizing keywords; it’s about designing systems that scale, perform, and adapt to evolving requirements.
The CREATE TABLE SQL command serves as the first step in database modeling, where logical schemas meet physical storage. A well-crafted table definition ensures data integrity through constraints like NOT NULL, UNIQUE, or FOREIGN KEY, while poor design leads to inefficiencies that cascade through applications. The challenge lies in balancing flexibility with rigidity—allowing for future expansion without sacrificing performance. Whether you’re building a user authentication system or a financial ledger, the decisions made during table creation will dictate how easily your database can handle queries, updates, and growth.
Modern database engines have evolved beyond basic table structures, incorporating features like partitioned tables, JSON columns, and temporal data types. Yet the core principle remains unchanged: every query, every join, and every optimization depends on the foundational work done during the CREATE TABLE phase. This guide dissects the mechanics, historical context, and strategic implications of SQL table creation, providing both a reference for syntax and a framework for architectural decision-making.
The Complete Overview of Create Table SQL
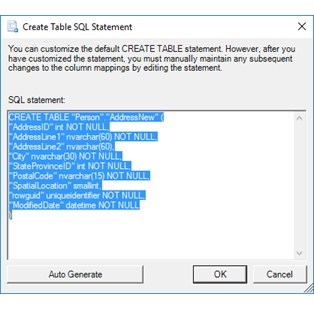
The CREATE TABLE statement is the linchpin of relational database management systems (RDBMS). At its core, it defines a structured container for data, specifying columns (attributes), their data types, and optional constraints that enforce rules. For example, a simple user table might include columns for user_id (integer), username (varchar), and email (varchar with a UNIQUE constraint). The syntax varies slightly across database vendors—MySQL, PostgreSQL, SQL Server—but the fundamental logic remains consistent. This uniformity allows developers to write portable SQL while leveraging vendor-specific extensions when necessary.
Beyond basic structure, the CREATE TABLE command enables the definition of relationships between tables through foreign keys, which link records across multiple tables. For instance, an orders table might reference a users table via a user_id column, creating a parent-child relationship. Advanced implementations may include indexes for performance optimization, default values for columns, or even computed columns that derive values from other fields. The flexibility of the CREATE TABLE syntax makes it adaptable to nearly any data modeling scenario, from simple key-value stores to complex hierarchical structures.
Historical Background and Evolution
The origins of the CREATE TABLE command trace back to the early 1970s, when Edgar F. Codd formalized the relational model at IBM. His theoretical work laid the groundwork for SQL, which was later standardized by ANSI in 1986. Early implementations, such as Oracle’s SQL*Plus and IBM’s DB2, introduced basic table creation syntax, but it wasn’t until the 1990s that features like constraints, triggers, and stored procedures became mainstream. The evolution of SQL reflected broader trends in computing—from mainframe-centric systems to client-server architectures—and the need for more expressive data modeling.
Table of Contents
- The Complete Overview of Create Table SQL
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can I add columns to an existing table without downtime?
- Q: What’s the difference between CREATE TABLE and CREATE TABLE AS SELECT ?
- Q: How do I ensure my table design follows third normal form (3NF)?
- Q: Are there performance penalties for using too many constraints?
- Q: Can I create a table with no columns?
- Q: How do I migrate a table from one database to another?
Today, the CREATE TABLE statement has expanded to include vendor-specific enhancements. PostgreSQL, for example, supports composite types and inheritance, while SQL Server introduces filetable and memory-optimized tables. These innovations address modern challenges, such as handling semi-structured data (via JSON/XML columns) or enabling real-time analytics. Despite these advancements, the core syntax remains a constant, ensuring backward compatibility while allowing for progressive enhancement. Understanding this history contextualizes why certain design patterns persist—such as normalization—and why newer features like partitioned tables are gaining traction.
Core Mechanisms: How It Works
The execution of a CREATE TABLE command involves several internal processes. When a database engine processes the statement, it first validates the syntax, checks for conflicts with existing objects, and allocates storage space based on estimated row size and expected growth. The engine then creates metadata entries in system catalogs (e.g., information_schema in PostgreSQL) to track the table’s structure, constraints, and permissions. This metadata is critical for query optimization, as the database planner uses it to determine the most efficient execution path for subsequent operations.
Under the hood, tables are stored as collections of rows and columns, with each column mapped to a specific data type (e.g., INT, VARCHAR, DATE). The storage engine (e.g., InnoDB in MySQL, Heap in SQLite) determines how data is physically organized, whether in row-based or columnar formats. Constraints like PRIMARY KEY or FOREIGN KEY are enforced at the transactional level, ensuring data integrity even in high-concurrency environments. For instance, a FOREIGN KEY constraint triggers a rollback if an insert operation violates referential integrity, maintaining consistency across related tables.
Key Benefits and Crucial Impact
The strategic use of CREATE TABLE SQL commands directly influences database performance, security, and scalability. A well-designed table structure minimizes redundant data through normalization, reduces query latency with proper indexing, and simplifies maintenance by enforcing constraints. Conversely, poorly structured tables lead to performance bottlenecks, such as excessive joins or bloated storage due to denormalization. The impact extends beyond technical metrics—it affects application development cycles, as schema changes often require migrations that disrupt workflows. Recognizing these trade-offs is essential for architects balancing immediate needs with long-term flexibility.
Modern applications demand more than just functional databases; they require systems that can adapt to changing business logic without costly overhauls. The CREATE TABLE command enables this adaptability through features like partitioning, which splits large tables into smaller, manageable segments, or by supporting temporal tables that track historical data. These capabilities reduce the need for manual archiving and simplify compliance with regulations like GDPR. The ability to extend table definitions—adding columns or altering constraints—without downtime further underscores the command’s role in maintaining agile infrastructure.
— Donald Knuth, "The Art of Computer Programming"
"Premature optimization is the root of all evil." Yet in database design, premature simplification is equally damaging. The
CREATE TABLEstatement is where thoughtful optimization begins—not by over-engineering, but by aligning structure with actual usage patterns.
Major Advantages
- Data Integrity: Constraints (e.g.,
NOT NULL,CHECK) ensure valid data entry, reducing application-level validation errors. - Performance Optimization: Proper indexing and partitioning via
CREATE TABLEreduce I/O overhead for frequent queries. - Scalability: Normalized designs minimize storage growth, while denormalization (when intentional) improves read performance.
- Security: Column-level permissions and encryption (e.g.,
ENCRYPTEDin PostgreSQL) can be defined during table creation. - Portability: Standard SQL syntax allows tables to be migrated across compatible RDBMS with minimal changes.
Comparative Analysis
| Feature | MySQL (InnoDB) | PostgreSQL | SQL Server |
|---|---|---|---|
| Partitioning Support | Yes (by hash, range, or key) | Yes (native partitioning) | Yes (partitioned tables) |
| JSON/XML Columns | Limited (5.7+) | Full support (JSONB type) | Full support (FOR JSON PATH) |
| Temporal Tables | No (requires triggers) | Yes (system-versioned tables) | Yes (built-in) |
| Default Constraints | Yes (column defaults) | Yes (with DEFAULT) |
Yes (with CONSTRAINT) |
Future Trends and Innovations
The next generation of CREATE TABLE SQL commands will likely focus on hybrid data models, blending relational structures with NoSQL flexibility. Vendors are already experimenting with "polyglot persistence" architectures, where tables can dynamically adjust schemas to accommodate semi-structured data (e.g., JSON documents stored in relational columns). Machine learning integration is another frontier—imagine a database that auto-optimizes table designs based on query patterns or predicts optimal indexing strategies. These advancements will reduce manual intervention while increasing adaptability to evolving workloads.
Cloud-native databases are also redefining table creation. Serverless offerings like Amazon Aurora or Google Spanner abstract storage management, allowing tables to scale horizontally without explicit partitioning commands. Meanwhile, edge computing introduces the need for lightweight, embedded databases where CREATE TABLE syntax must be optimized for minimal resource usage. The future of SQL table design lies in balancing standardization with innovation—preserving the reliability of relational models while embracing the agility of modern data architectures.
Conclusion
The CREATE TABLE SQL command is more than a syntactic tool; it’s the first step in building systems that store, retrieve, and protect data. Mastery of this command requires an understanding of both its technical implementation and its role in broader database strategies. Whether you’re designing a high-transaction e-commerce platform or a data warehouse for analytics, the decisions made during table creation will shape performance, security, and maintainability for years to come. As databases grow more complex, the principles of good table design—normalization, indexing, and constraint enforcement—remain timeless.
For developers, the key takeaway is to treat CREATE TABLE as an iterative process. Start with a minimal schema, validate it through testing, and refine it based on real-world usage. Leverage vendor-specific features when they provide clear advantages, but prioritize portability and clarity. The best table designs are those that evolve with the application, not those that constrain it. By approaching CREATE TABLE with both precision and foresight, you lay the foundation for robust, scalable databases.
Comprehensive FAQs
Q: Can I add columns to an existing table without downtime?
A: Yes, most RDBMS support ALTER TABLE ADD COLUMN with minimal disruption. However, adding a NOT NULL column to a populated table may require a default value or downtime for backfills. Always test in a staging environment first.
Q: What’s the difference between CREATE TABLE and CREATE TABLE AS SELECT?
A: CREATE TABLE defines a new structure from scratch, while CREATE TABLE AS SELECT (CTAS) creates a table by populating it with query results. CTAS is useful for materialized views or snapshots but doesn’t support constraints like PRIMARY KEY in all databases.
Q: How do I ensure my table design follows third normal form (3NF)?
A: 3NF requires:
1. Removing transitive dependencies (e.g., user_address.city should reference a separate cities table).
2. Using foreign keys to eliminate redundant data.
3. Avoiding composite keys unless necessary.
Tools like EXPLAIN ANALYZE can later verify performance implications.
Q: Are there performance penalties for using too many constraints?
A: Constraints like FOREIGN KEY or CHECK add overhead during writes but improve read performance by reducing application-side validation. Benchmark with your workload—some systems benefit from deferring constraints (DEFERRABLE in PostgreSQL).
Q: Can I create a table with no columns?
A: Technically yes, but such tables are useless for storage. Some databases (e.g., PostgreSQL) allow empty schemas, though they violate relational principles. Use cases might include placeholder tables for future expansion or schema migration scripts.
Q: How do I migrate a table from one database to another?
A: Use CREATE TABLE ... LIKE (MySQL) or pg_dump (PostgreSQL) to replicate structure, then export/import data with tools like mysqldump or SQL Server Data Tools. For schema differences, write a custom script to map data types (e.g., VARCHAR(255) → TEXT).
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.