Unlocking Insights: What Is the Range of a Data Set and Why It Matters

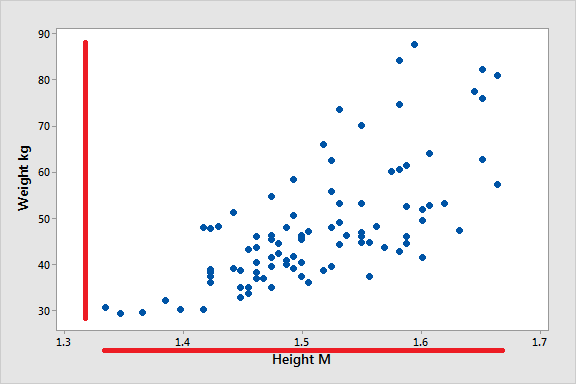
Understanding what is the range of a data set is foundational to interpreting variability in numbers. It’s the simplest yet most revealing measure of spread—just the difference between the highest and lowest values. Yet, its power lies in how it exposes outliers, skewness, or inconsistencies that mean averages alone might miss. For instance, a real estate dataset with prices ranging from $100K to $5M reveals far more about market dynamics than the median alone.
The range isn’t just a statistical curiosity; it’s a decision-making lever. In quality control, a narrow range in manufacturing tolerances signals precision. In finance, a wide range in stock returns flags volatility. Even in sports analytics, the range of player speeds can predict game outcomes. Yet, its simplicity belies nuance: context dictates whether a range of 10 or 1,000 units is meaningful.
Misinterpretation here can lead to costly errors. A dataset’s range might be distorted by extreme values—what statisticians call sensitivity to outliers. Ignoring this can skew risk assessments, budget forecasts, or even medical diagnostics. The key lies in pairing the range with other metrics (like interquartile range or standard deviation) to paint a fuller picture.
The Complete Overview of What Is the Range of a Data Set
At its core, what is the range of a data set refers to the arithmetic difference between the maximum and minimum values in a collection of numbers. It’s a measure of dispersion, quantifying how spread out the data points are. For example, in a dataset of daily temperatures—[72, 68, 80, 75, 65]—the range is 80 − 65 = 15°F. This single figure instantly communicates variability without needing deeper analysis.The range’s utility extends beyond basic arithmetic. It serves as a quick sanity check for data quality: an unusually large range might indicate errors (e.g., a mislabeled $100M sale in a $50K dataset). Conversely, a near-zero range suggests uniformity, which could be desirable in controlled experiments or problematic in diverse populations. Its simplicity makes it indispensable in exploratory data analysis (EDA), where speed and intuition matter most.
Historical Background and Evolution
The concept of range predates modern statistics, emerging from early attempts to summarize large datasets. In the 18th century, astronomers like Edmond Halley used simple measures of spread to analyze celestial observations, though they lacked formal terminology. By the 19th century, statisticians like Karl Pearson and Francis Galton formalized descriptive statistics, elevating the range to a standard tool alongside mean and median.Its evolution reflects broader shifts in data science. Initially, range was used in engineering to assess material consistency (e.g., tensile strength of steel). Later, with the rise of computing, it became a building block for more complex metrics like variance and standard deviation. Today, it’s a cornerstone of machine learning preprocessing, where feature scaling often relies on understanding a dataset’s range to normalize inputs.
Core Mechanisms: How It Works
Calculating what is the range of a data set follows a straightforward formula:Range = Maximum Value − Minimum Value.
For a dataset like [12, 18, 14, 22, 10], the steps are:
1. Identify the maximum (22) and minimum (10).
2. Subtract: 22 − 10 = 12.
Table of Contents
- The Complete Overview of What Is the Range of a Data Set
- Historical Background and Evolution
- Core Mechanisms: How It Works
- Key Benefits and Crucial Impact
- Major Advantages
- Comparative Analysis
- Future Trends and Innovations
- Conclusion
- Comprehensive FAQs
- Q: Can the range be negative?
- Q: How does the range differ from the interquartile range (IQR)?
- Q: Is the range affected by the number of data points?
- Q: What’s the relationship between range and standard deviation?
- Q: When should I use the range instead of other spread metrics?
- Q: How do I calculate the range in Python?
- Q: Can the range be used for categorical data?
However, the mechanics grow nuanced with real-world data. Missing values or categorical data (e.g., colors) require preprocessing. For time-series data, ranges might be calculated per interval (e.g., hourly stock prices). Even in big data, distributed systems must handle edge cases where min/max values aren’t immediately accessible without aggregation.
The range’s sensitivity to outliers is both its strength and weakness. A single extreme value can inflate the range artificially, masking the true distribution. This is why practitioners often pair it with the interquartile range (IQR), which focuses on the middle 50% of data, or use modified ranges (e.g., excluding top/bottom 5% of values).
Key Benefits and Crucial Impact
The range’s impact spans industries where variability directly influences outcomes. In manufacturing, a tight range in product dimensions ensures consistency; in healthcare, a wide range in blood pressure readings might signal hypertension risk. Even in social sciences, range helps compare income inequality across regions. Its ability to highlight extremes makes it a red flag for anomalies—whether in fraud detection or sensor malfunctions.Beyond practical use, the range is a pedagogical tool. It introduces beginners to the idea of data spread without overwhelming them with complex formulas. For advanced analysts, it’s a quick diagnostic: a range that’s too large or small can prompt deeper investigation into data collection methods or underlying processes.
"The range is the simplest measure of spread, but its implications are profound. It doesn’t just describe data—it challenges assumptions about what ‘normal’ looks like." — John Tukey, Statistician & Data Science Pioneer
Major Advantages
- Speed and Simplicity: Computed in seconds, requiring only two values. Ideal for rapid assessments in fields like emergency response or quality control.
- Outlier Detection: An unusually large range signals potential data errors or rare events (e.g., a single $1B sale in a $100K dataset).
- Resource Efficiency: No need for advanced tools—calculable by hand or in basic software (Excel, Python’s `max()`/`min()` functions).
- Contextual Flexibility: Applicable to any numerical dataset, from sensor readings to survey responses.
- Foundation for Advanced Metrics: Used to derive standard deviation, variance, and confidence intervals, which rely on understanding a dataset’s spread.

Comparative Analysis
| Metric | What It Measures |
|---|---|
| Range (Max − Min) | Total spread of all data points; sensitive to outliers. |
| Interquartile Range (IQR) | Spread of the middle 50% of data; robust to outliers. |
| Standard Deviation | Average distance from the mean; influenced by all data points. |
| Variance | Square of standard deviation; emphasizes extreme deviations. |
Future Trends and Innovations
As data grows more complex, the range’s role is evolving. In big data, distributed computing frameworks (like Apache Spark) optimize range calculations across petabytes of data. Machine learning increasingly uses range-based feature scaling (e.g., Min-Max scaling) to prepare data for algorithms like neural networks. Meanwhile, real-time analytics demand faster range computations, driving innovations in streaming data processing.Emerging fields like quantum computing may redefine how ranges are calculated, leveraging parallel processing to handle multivariate ranges efficiently. Even in explainable AI, ranges help interpret model outputs by showing input feature variability’s impact on predictions. The future lies in integrating range with other metrics into automated anomaly detection systems, where context-aware ranges could flag issues without human intervention.
Conclusion
What is the range of a data set is more than a basic statistic—it’s a lens through which data’s true nature is revealed. Its simplicity belies its critical role in quality assurance, risk management, and exploratory analysis. Yet, its limitations (outlier sensitivity) remind us that no single metric tells the whole story. By pairing the range with complementary tools, analysts can uncover patterns, validate hypotheses, and make decisions grounded in data.The next time you encounter a dataset, ask: What does the range reveal? The answer might just change how you interpret the numbers—and act on them.
Comprehensive FAQs
Q: Can the range be negative?
A: No. Since range is calculated as Max − Min, and Max is always ≥ Min in numerical datasets, the result is non-negative. A negative result would imply data corruption or incorrect sorting.
Q: How does the range differ from the interquartile range (IQR)?
A: The range captures the full spread of data (Max − Min), while the IQR focuses on the middle 50% (Q3 − Q1). The IQR is less sensitive to outliers, making it more reliable for skewed distributions.
Q: Is the range affected by the number of data points?
A: Directly, no—the range depends only on the highest and lowest values. However, with more data points, the likelihood of extreme values (and thus a larger range) may increase, especially in unbounded distributions.
Q: What’s the relationship between range and standard deviation?
A: The range provides a rough upper bound for standard deviation (since SD ≤ Range/2 in symmetric distributions), but it doesn’t account for how data points are distributed around the mean. Standard deviation considers all values’ deviations from the mean.
Q: When should I use the range instead of other spread metrics?
A: Use the range for:
Q: How do I calculate the range in Python?
A: Use `max(data) - min(data)` for a list `data`. For Pandas DataFrames, apply `df.max() - df.min()` to columns. Example:
```python
import numpy as np
data = [5, 2, 9, 1]
range_value = np.max(data) - np.min(data) # Output: 8
```
Q: Can the range be used for categorical data?
A: No. The range is strictly for numerical data. For categorical data, use frequency counts or entropy measures to assess variability.
Leave a Comment
Comments are moderated before appearing. The data you submit is processed according to the Privacy Policy of Sac.